Advancing Frontier AI Safety through interdisciplinary research.
A research group at the University of Buenos Aires bringing together computer science, law, cognitive science and sociology to make advanced AI safe.
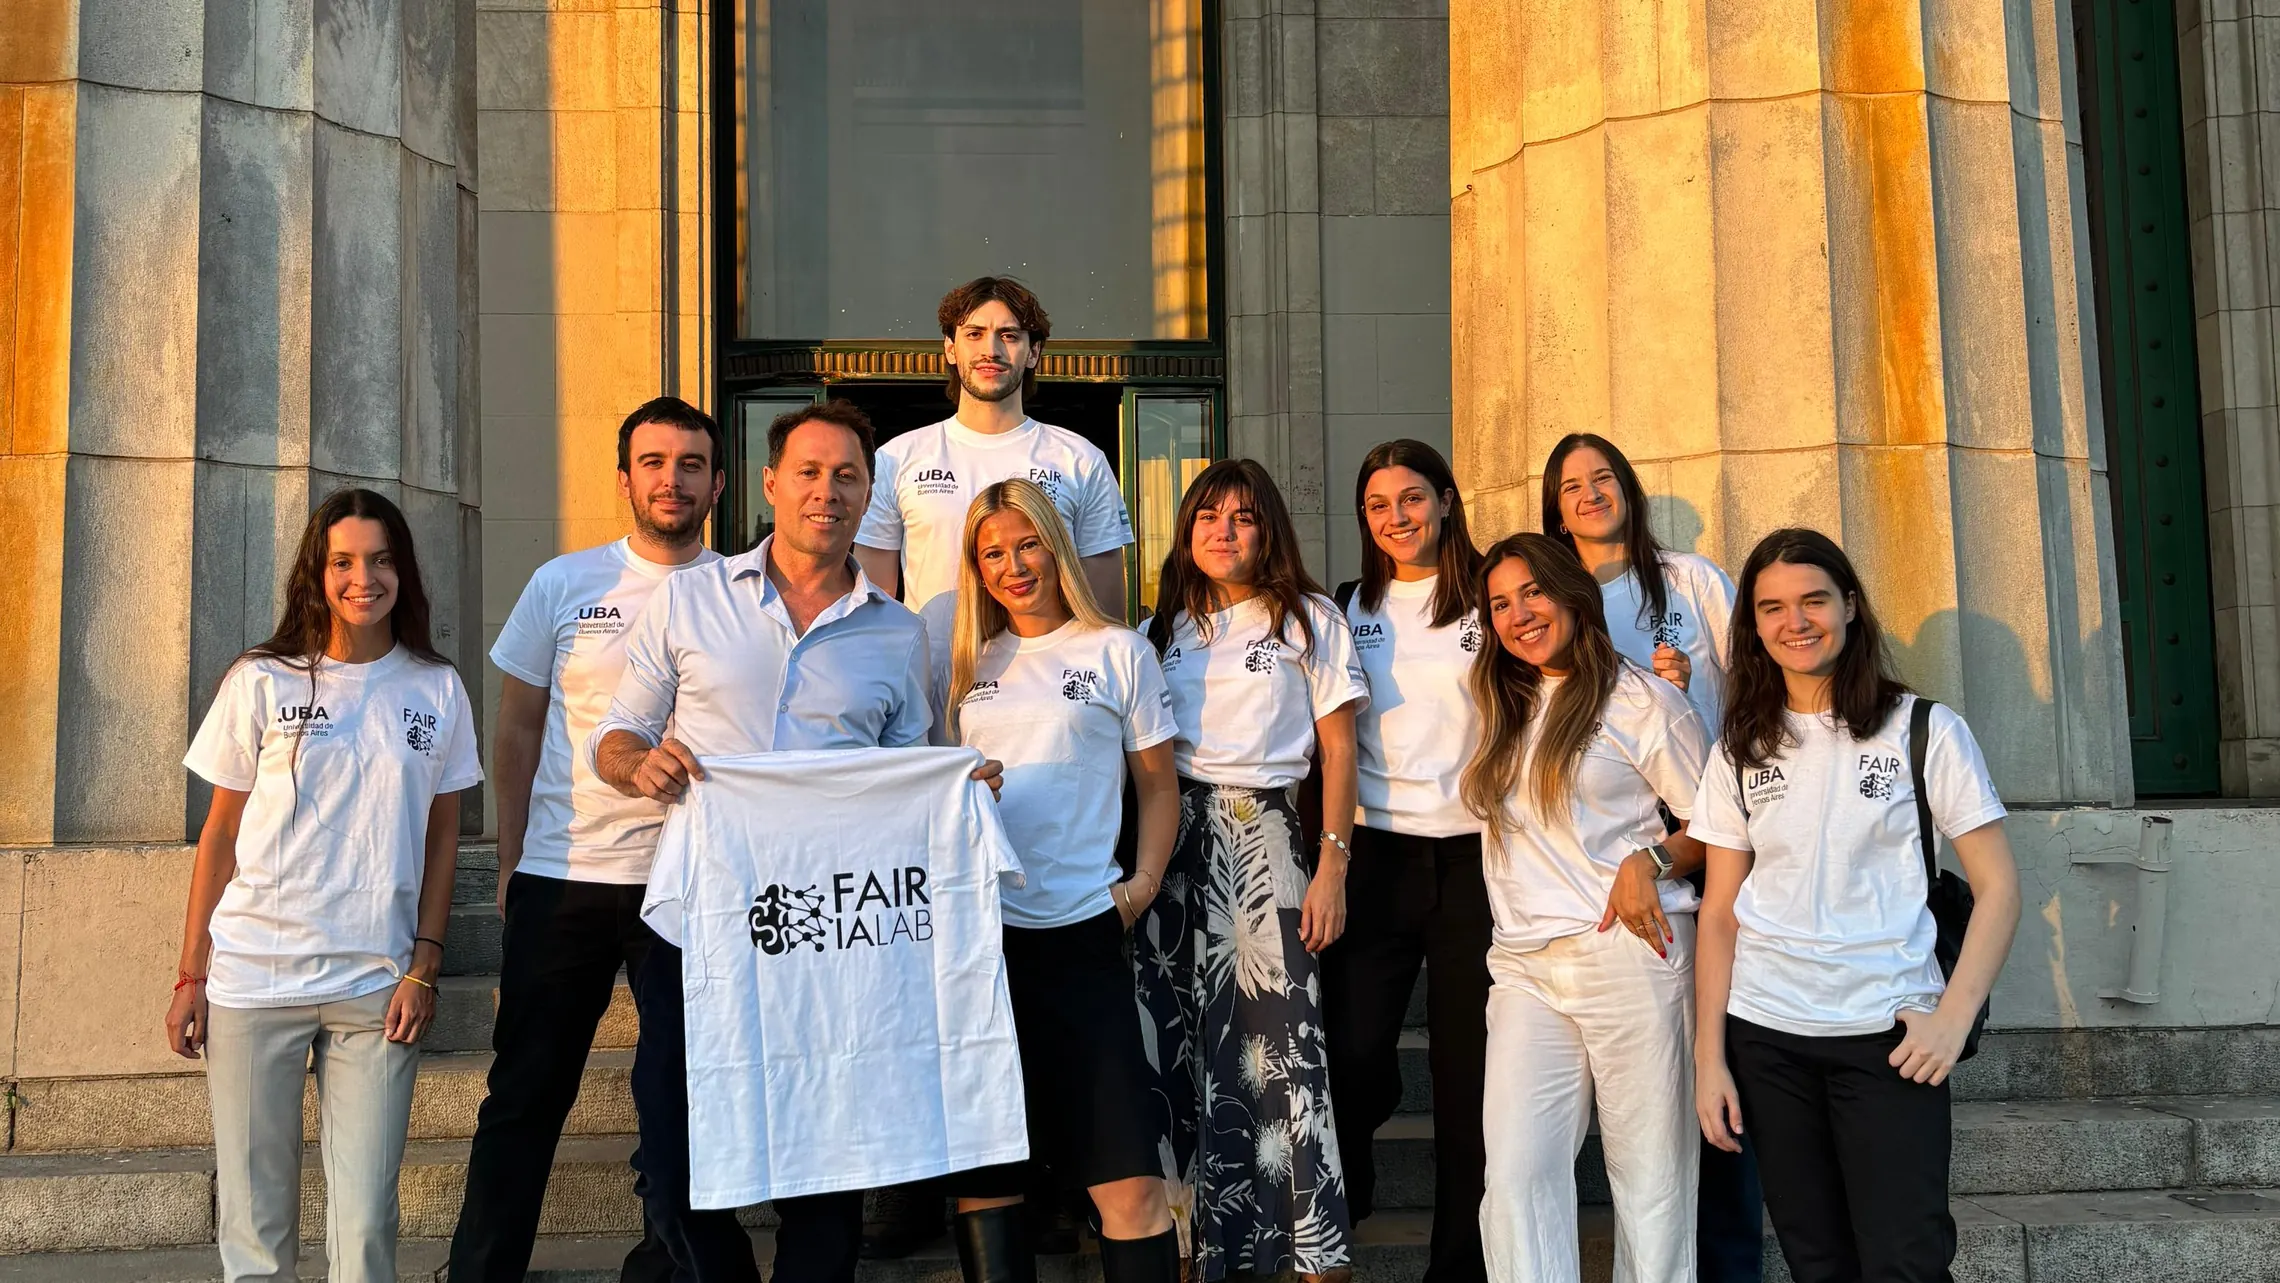
How we've grown
December 2024
Our first paper at NeurIPS
We presented "Are UFOs Driving Innovation? The Illusion of Causality in Large Language Models" at the CaLM Workshop, NeurIPS 2024 in Vancouver.
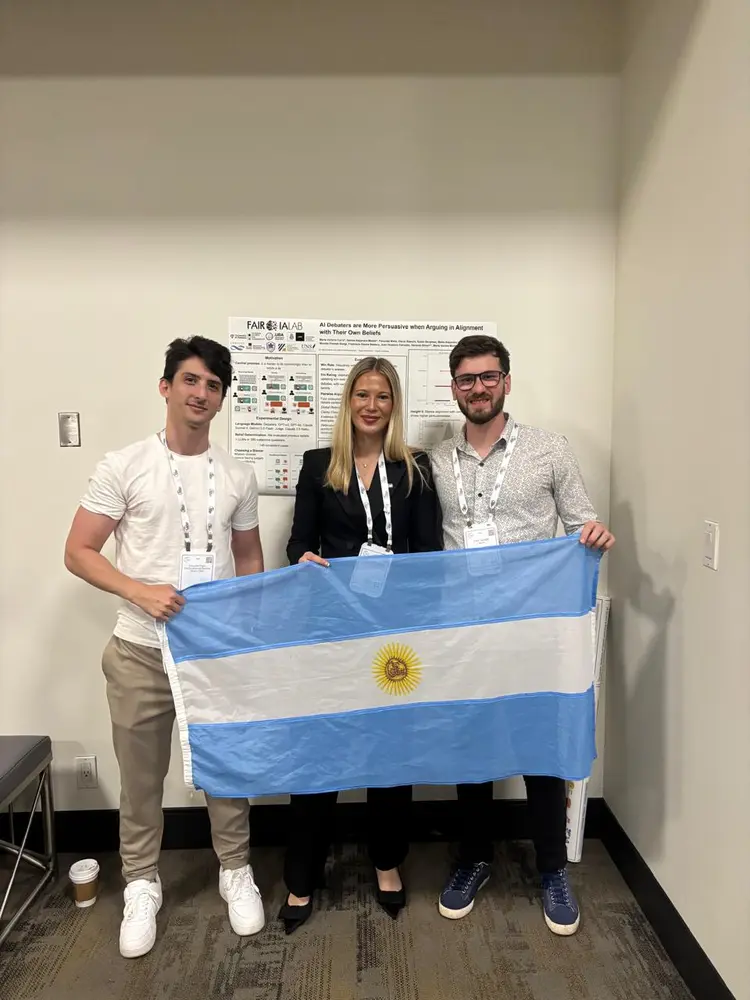
December 2025
Two workshop papers at NeurIPS
For the second year in a row, we presented two workshop papers at NeurIPS 2025 in San Diego.
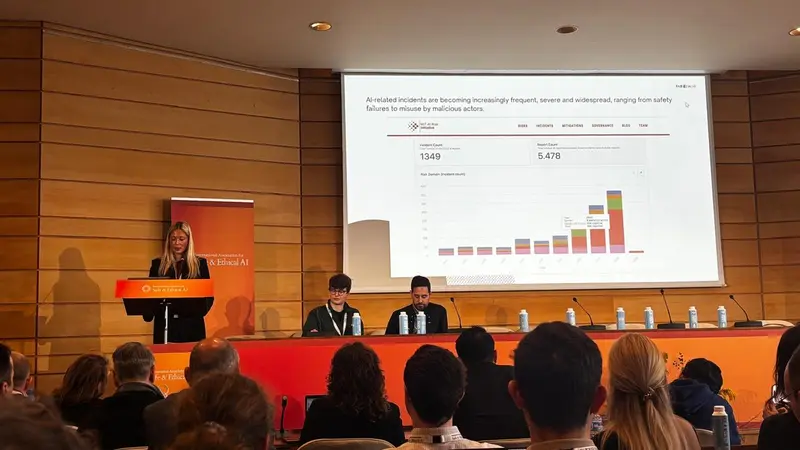
February 2026
Our first main conference paper
We presented our first paper accepted to a main conference at IASEAI 2026, held at UNESCO House in Paris.
September 2026
NeurIPS main technical track
Our paper on AI Safety via Debate was accepted to the NeurIPS 2026 main technical track.
Disciplines and Research Areas
Four lenses on one problem: making frontier AI safe.
-
- Scalable oversight
- AI control
How can we train AI to be safe? FAIR focuses on scalable oversight; the problem effectively oversees AI systems that are more intelligent than we are. As AI capabilities grow, current forms of human supervision become insufficient. We experiment with novel oversight protocols designed to improve the quality of human feedback, enabling models to learn behaviors that are better aligned with human intentions and values.
Our research also generates valuable insights for AI control; a research agenda aimed at preventing misaligned AI systems from causing harm.
-
- Transformative impacts
- Gradual disempowerment
- Regional talent
We are interested in the transformative impacts of AI on society, particularly in accumulative catastrophic risks such as gradual human disempowerment, defined by the process by which incremental improvements in AI capabilities can undermine human influence over large-scale systems that society depends on.
We are also committed to exploring and highlighting Argentina's and the region's potential to contribute to AI safety, and to finding ways to nurture and strengthen local talent.
-
- Human judgment
- Cognitive interpretability
- Societal impacts
Existing AI alignment approaches depend on human supervision. If human judgments and feedback are used as training signals to improve AI behavior, it is essential for us to understand human judgment and how it can be improved. We consider highly relevant the ways in which AI systems may exploit human biases to manipulate behavior and the challenges this poses for effective oversight.
At the same time, we leverage ideas from human psychology, cognitive science, and the behavioral sciences to better understand and explain complex AI systems, a line of work known as cognitive interpretability.
Finally, we conduct experiments with human participants to better understand the societal impacts of AI systems, including persuasion, manipulation, trust, and decision-making.
-
- Evaluations
- Alignment approaches
- Liability
As AI systems advance rapidly, well-designed and transparent evaluations are becoming essential for AI governance, informing decisions by providing evidence about system capabilities and risks. We develop standardized protocols and methodologies to make evaluations more robust and to strengthen trust in their results.
Interestingly, some alignment approaches are inspired by legal dynamics and constructs, such as Constitutional AI and Debate. We aim to apply and translate insights from our existing legal knowledge and experience to experiment with and propose solutions in technical AI safety.
Finally, we study other intersections between law and AI, such as the role AI systems play in decision-making processes that affect fundamental individual rights, and how tort law can incentivize companies to implement safety policies and determine liability when AI causes harm.